



By Felix Chen, Stephan Rabanser, Sayash Kapoor, and Arvind Narayanan. See the full author list and affiliations here.
There are growing calls for independent and embedded AI evaluation, especially of AI agents. But much remains unclear: what constitutes a “good” evaluation, what needs to be evaluated in the first place, and how best to coordinate and support the influx of people entering the burgeoning evaluation ecosystem.
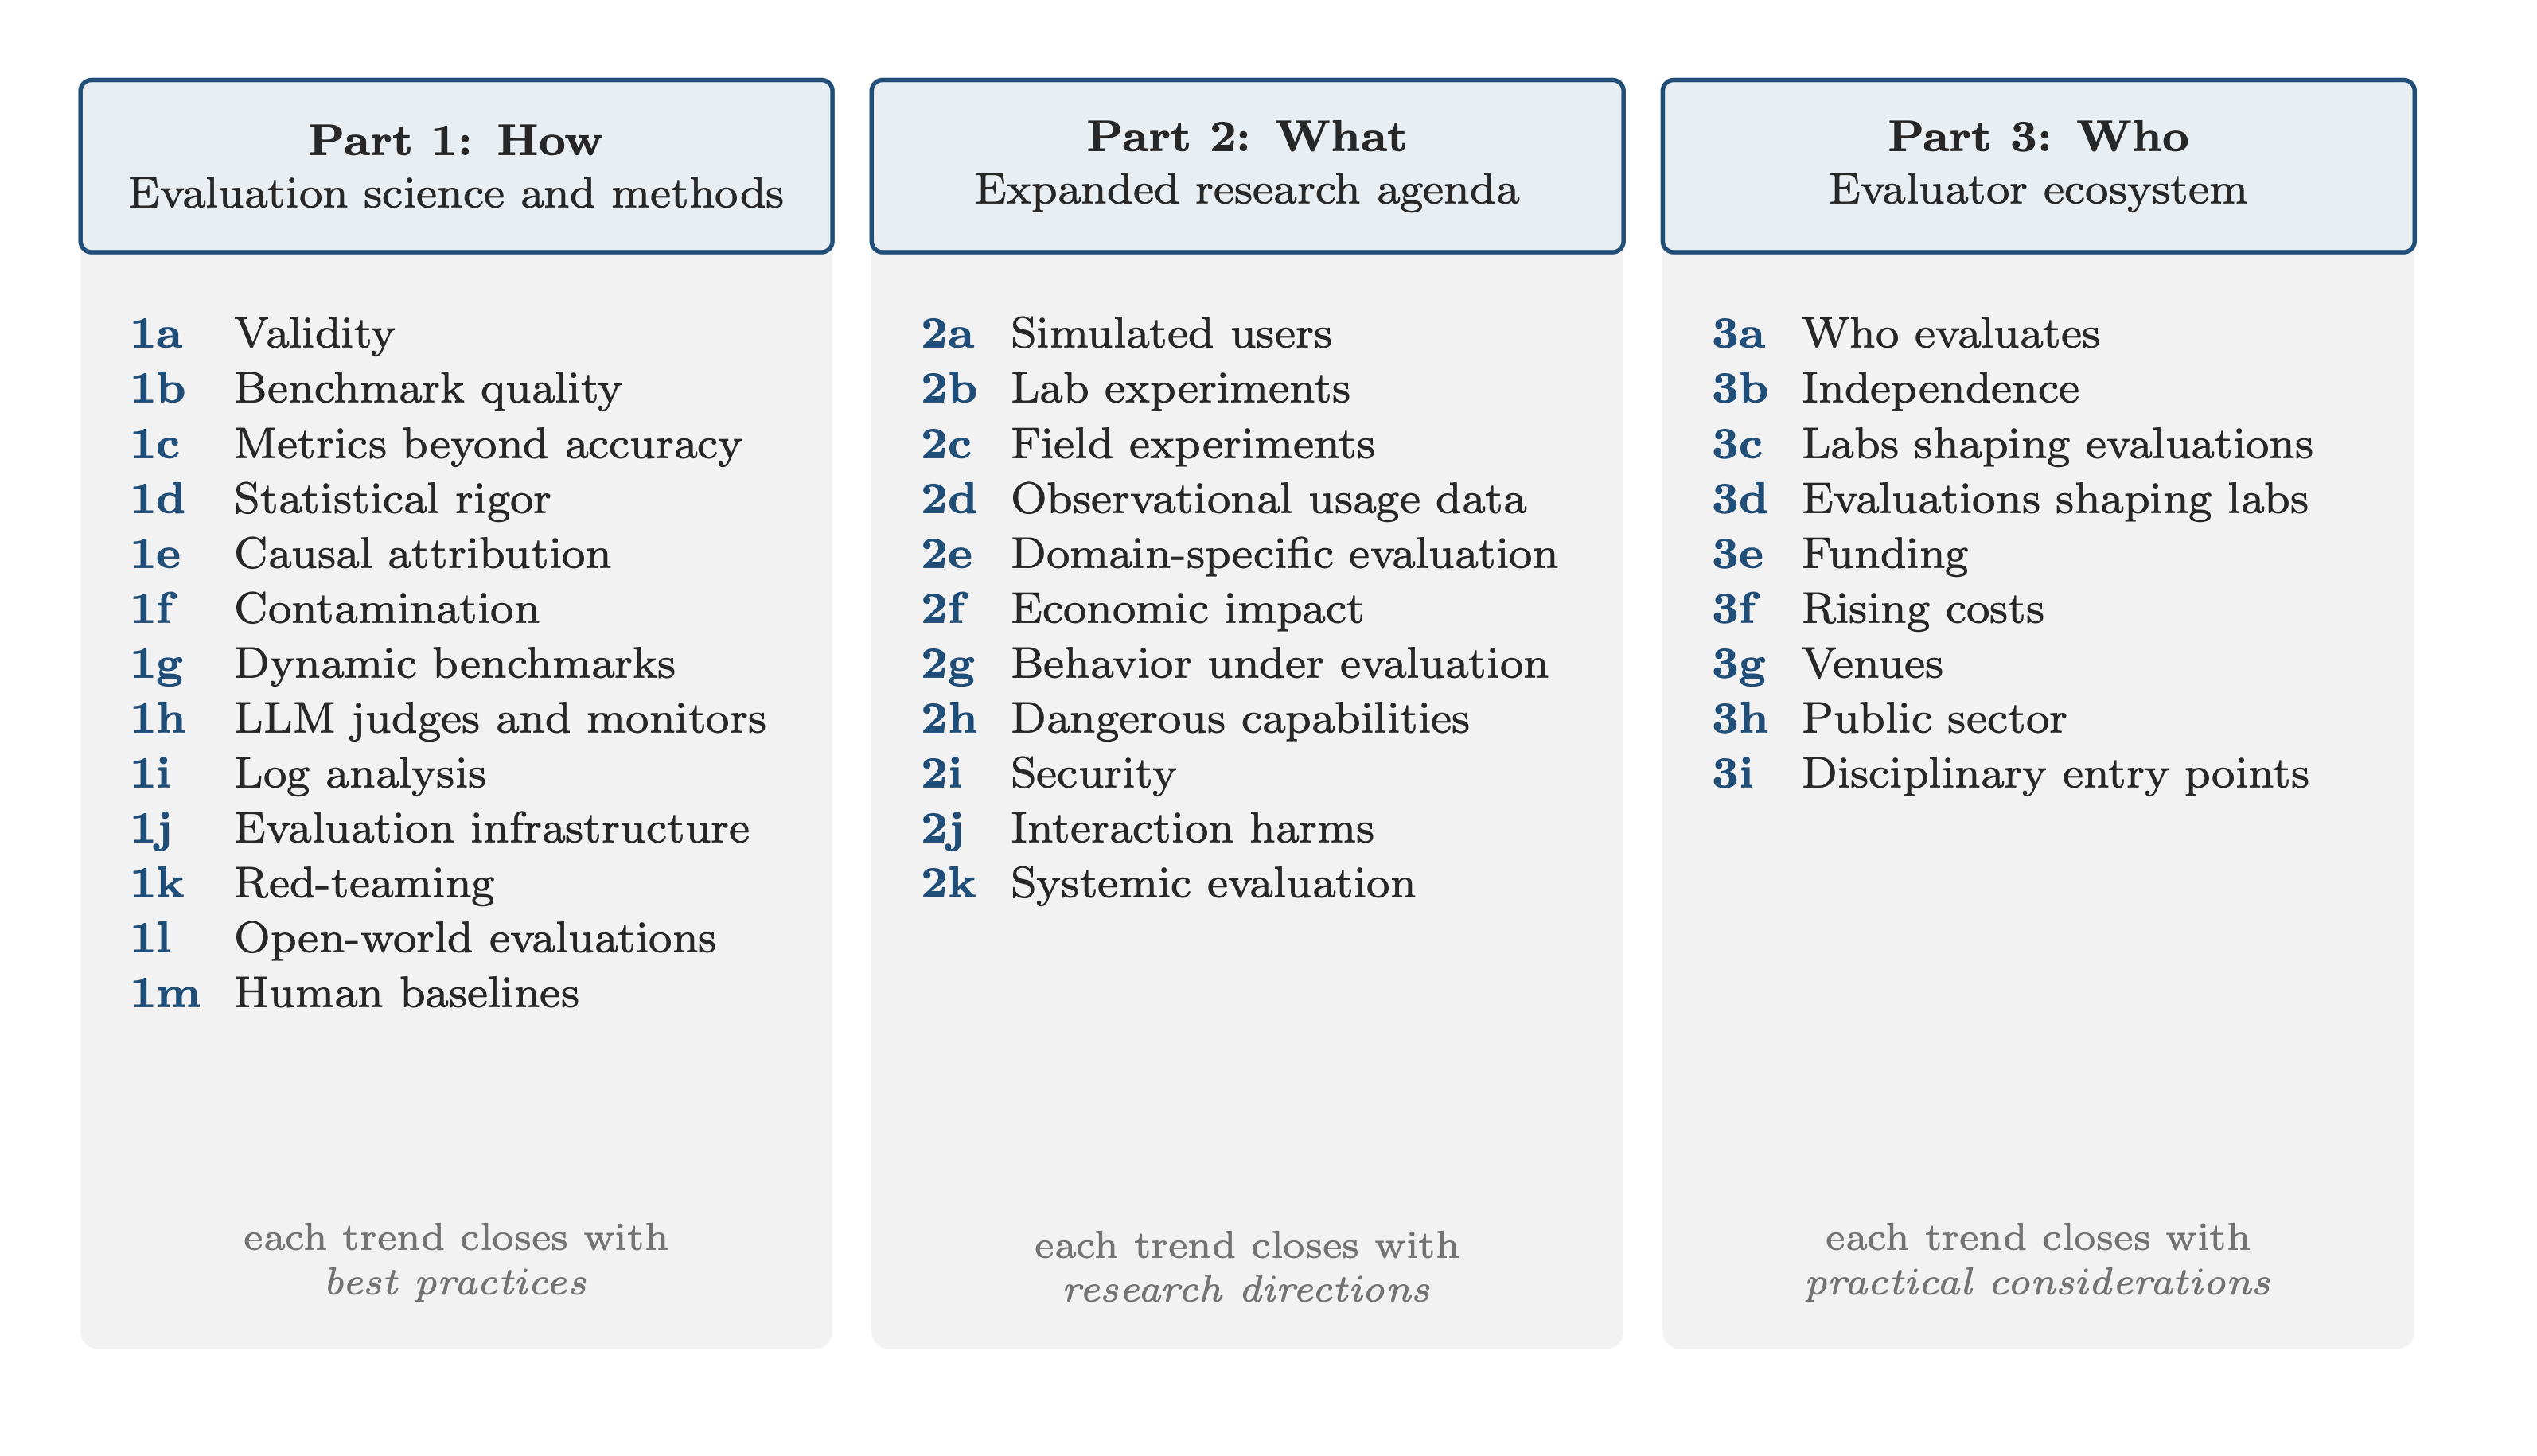
Our group at Princeton has been working to improve the state of AI agent evaluation for about three years. We teamed up with people who’ve done foundational work on evaluation at Stanford, the UK AI Security Institute, and Brookings. Our paper is titled Emerging Trends in AI Agent Evaluation. We synthesized the trends we see across three dimensions—the science and methods, the research agenda, and the evaluation ecosystem—with the goal to help those who are upskilling for this new paradigm. We also aim to equip evaluators, funders, and the public with a set of questions to ask, and provide actionable recommendations.
Challenges for agents, new and old
AI developers have long made claims about the real-world performance of their systems based on benchmark scores. It is harder now to assess whether the evidence gathered supports claims made about agents. The evaluator must scrutinize the entire trajectory, not just the final outcome. It is important, for example, to know if agents took shortcuts, particularly since they have access to tools and environments. And when agents perform better or worse, it is harder to attribute these changes to different components of the agent. Addressing these concerns requires significant engineering effort, and the work is getting increasingly expensive—for example, several agents on the ExploitBench benchmark cost tens of thousands of dollars in credits to evaluate. These numbers also don’t factor in the significant engineering effort needed to set up and maintain the evaluation infrastructure itself.
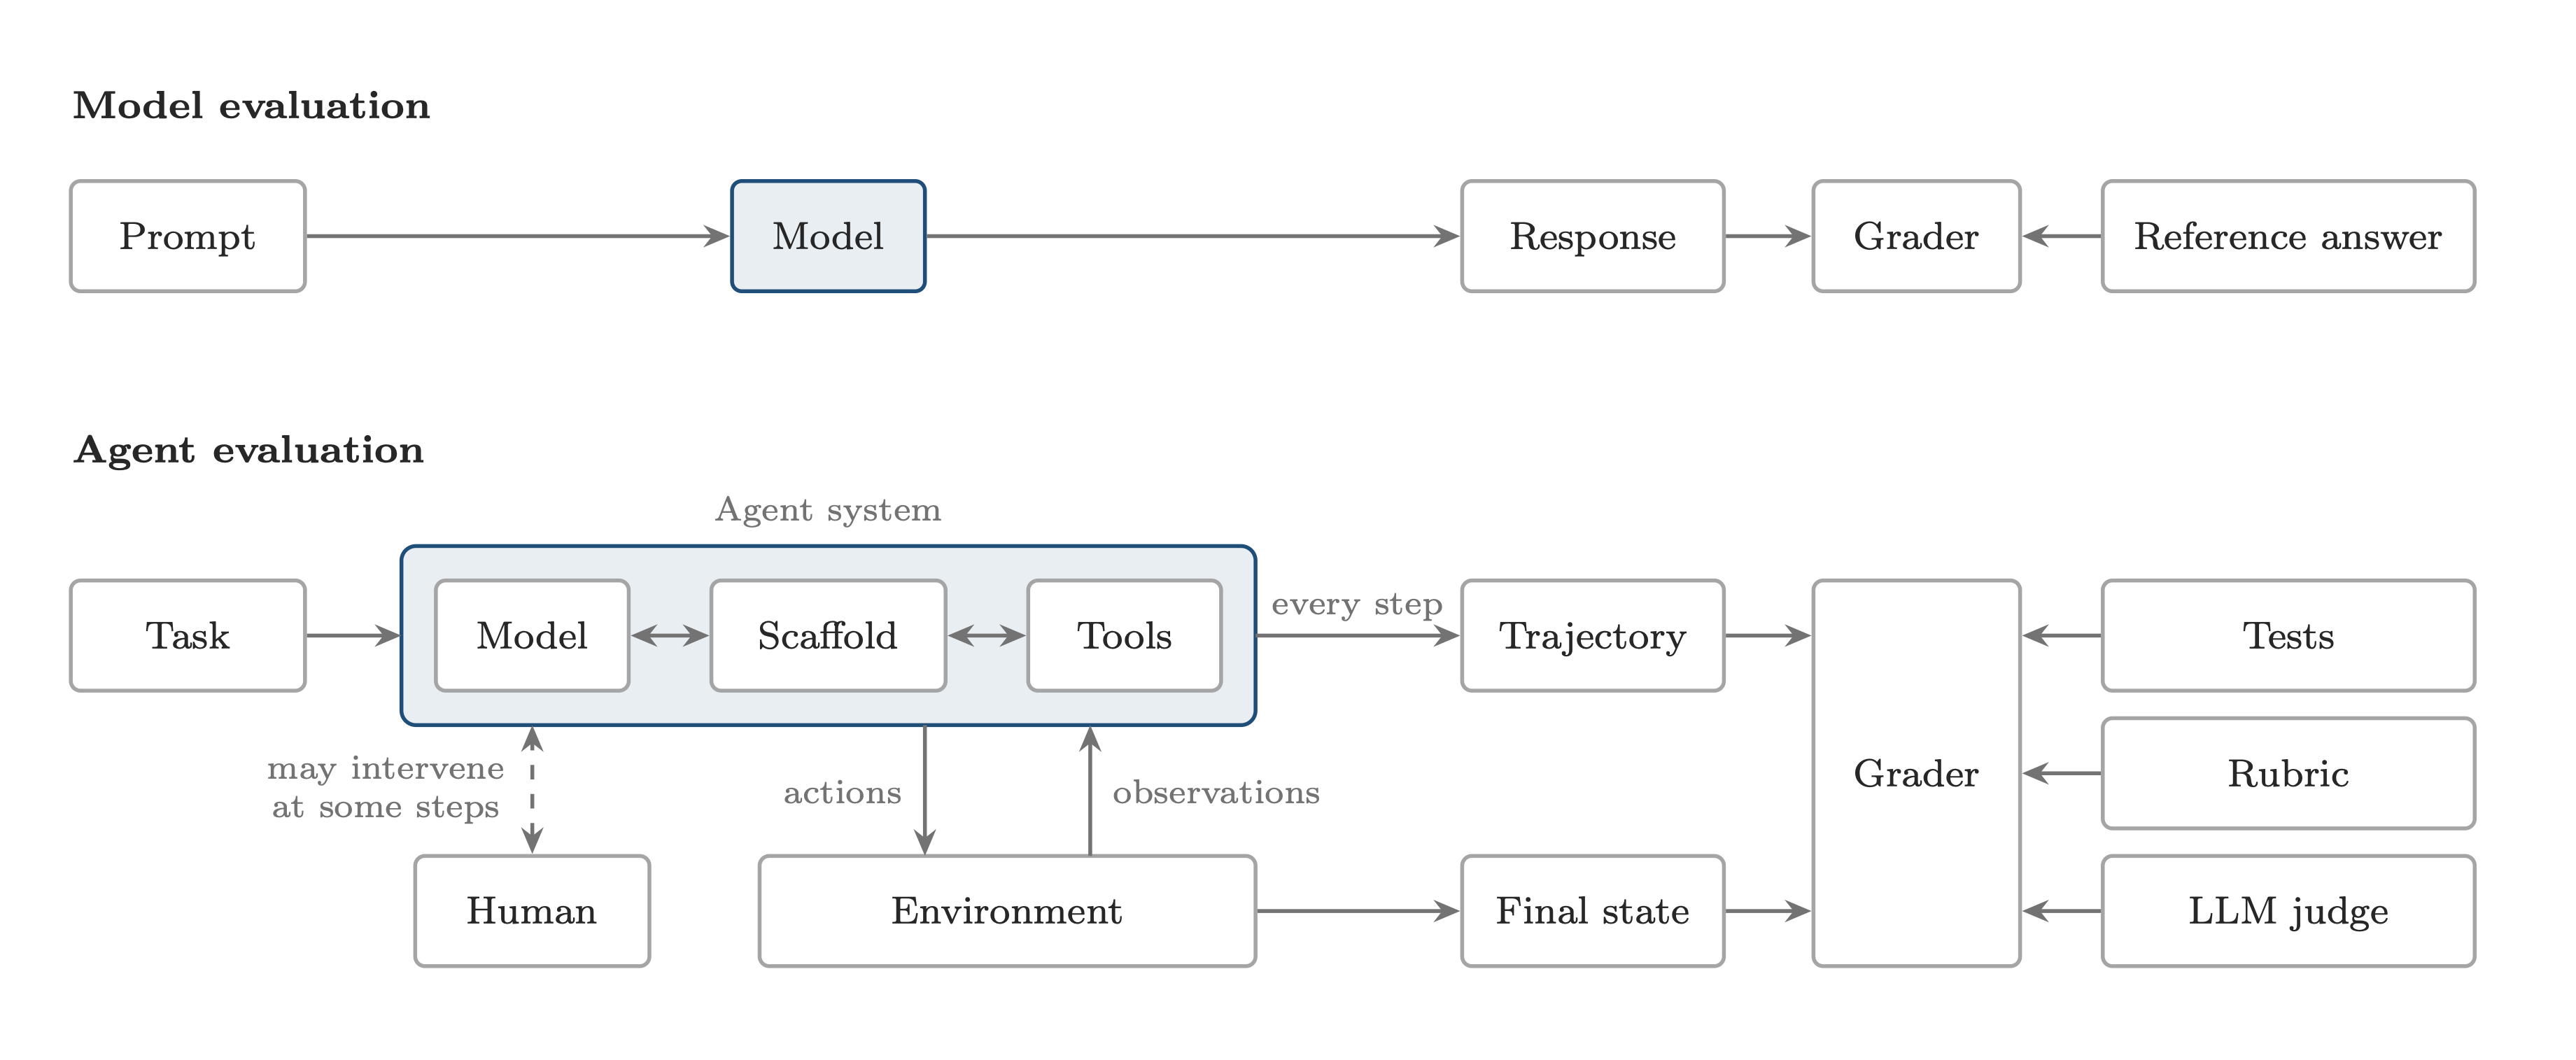
Faced with the massive volume of traces that agents generate, evaluators are also struggling to inspect and monitor these agents at scale. The tools evaluators rely on today to do this work are not foolproof—and themselves require evaluation. To investigate the recent OpenAI-HuggingFace incident after the fact, evaluators relied upon other agents to look for and identify instances of harmful action, an approach they acknowledged carried its own limitations and biases.
Because agents are deployed in dynamic settings (and increasingly together with other agents), it is harder to design good metrics to capture the underlying concepts of interest, and create valid conditions to implement them. Addressing these challenges will require better tools, more rigorous benchmarks, and experimentation with different approaches and formats, such as through open-world evaluations and growing observational data on real-world usage.
The scope of evaluation needs is growing
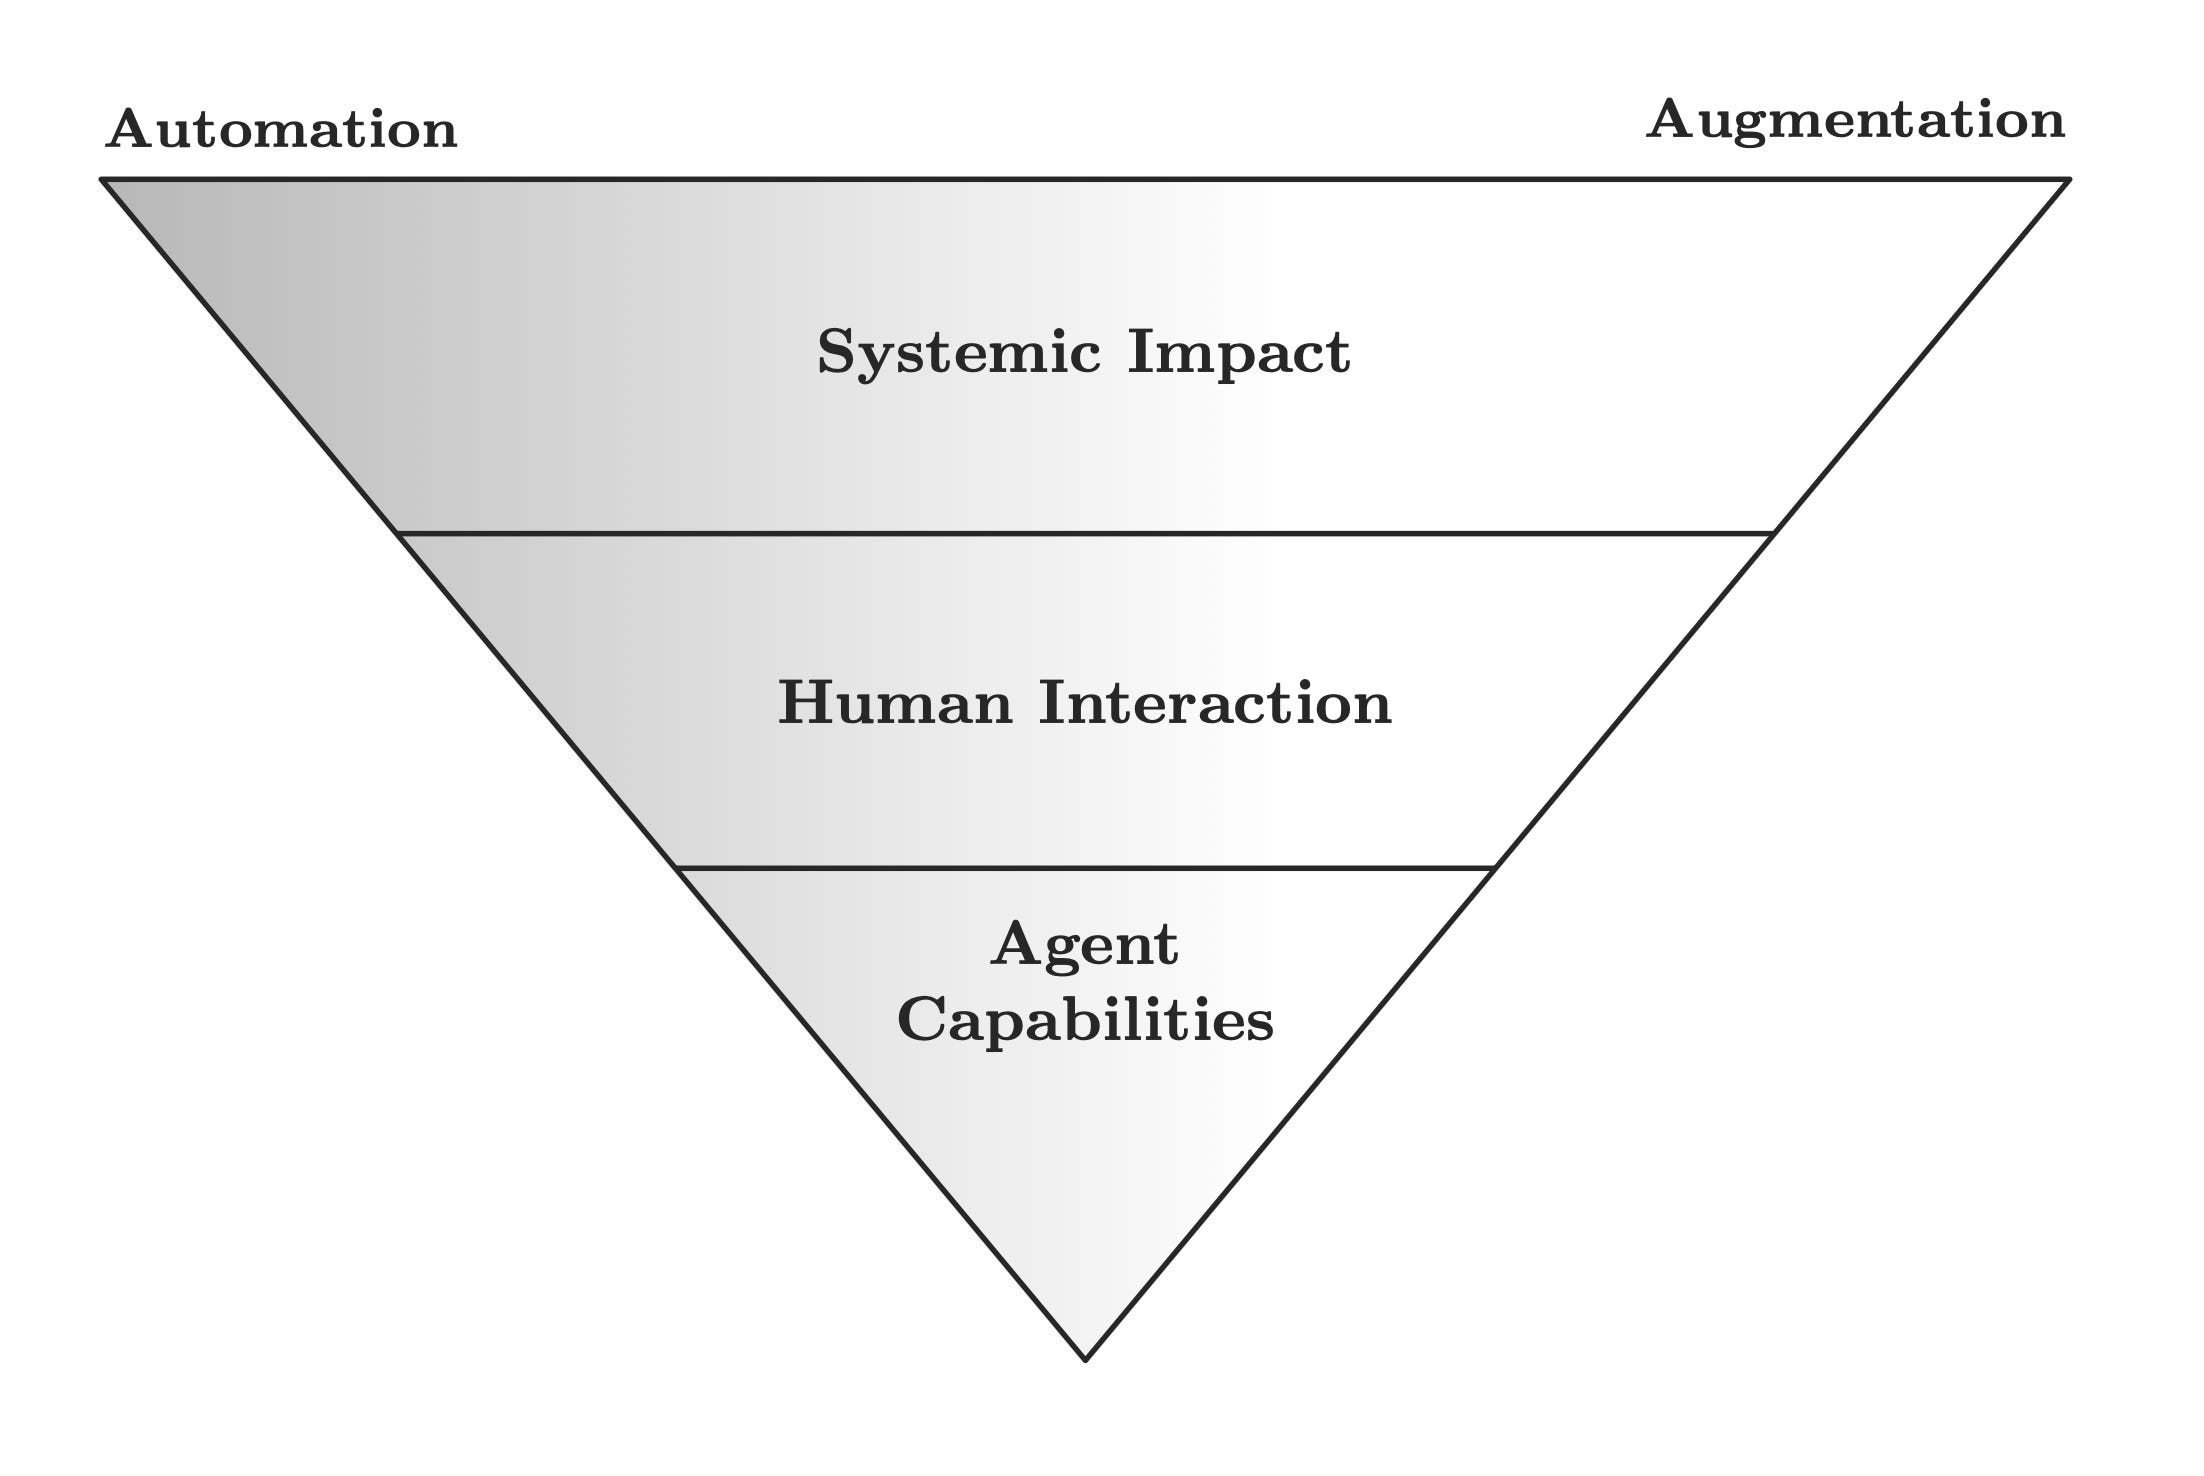
Crucially, the results of evaluation at one level of scope are not guaranteed to translate to another. An agent might demonstrate capability in the lab, but face limits when placed in a specific use case. Consider METR’s randomized controlled trial which found that, despite expectations, usage of agent tools toward software development actually increased overall completion time on the tasks at hand. Agents may be able to perform certain tasks, but how that capability translates for humans in the real world requires evaluation in context. An expanded research agenda is therefore needed to understand agents at each level: their capabilities, their interactions with humans, and their impact on institutions and incentive structures. This work requires both technical and sociotechnical evaluation to study not just the agent itself but the agent(s) in context.
Across these different layers, evaluators have a choice in framing the questions they ask and the findings they generate. Can an agent automate a task or process? Or, can an agent augment the work of a human? These are two complementary lenses. If evaluation largely focuses on how agents automate certain tasks, we will better understand where and how human work can be replaced. But it won’t tell us how humans can better collaborate using agents, or how agents can improve human work.
Who gets to evaluate and how?
This expanded research agenda will require an expanded set of evaluators from a mix of disciplines. It will also require that evaluators have the freedom to choose which questions to pursue and how. When evaluators with different approaches agree, we might gain greater confidence in those results. And when they conflict, evaluators can identify vague definitions and limitations to their findings.
Who gets to participate, and with what independence, will shape the questions evaluators ask and the methods they use. Meaningful independence is influenced by several factors. As the costs of frontier evaluation keep increasing, the ability of independent evaluators to participate will be increasingly determined by their access to increased funding. Whether independent evaluators have sufficient access to models also impacts their ability to measure and assess the true frontier. Questions of access now also extend to Chain of Thought traces for agents, since frontier labs now release summarized versions instead of raw traces. Alongside these challenges, evaluators also need to navigate whether they can conduct work without fear of retaliation, and how they can transparently share their findings.
Where do we go from here?
There is a clear window now to bring in new participants, methods, and ideas for agent evaluations, and to meet the pressing need for rigorous evidence in a fast-moving space. We hope this paper gives readers an emerging sense of the field’s direction. There are many steps that stakeholders in the AI evaluation community can take to advance the science and practice of AI evaluation.
For prospective evaluators, there is a need to determine what roles or questions within this ecosystem best fit their expertise, and examine which dimensions of independence are required for that work. In particular, we encourage participation from disciplines not yet engaged in AI evaluation; there are many open challenges that can benefit from their perspectives.
For current evaluators, there is an opportunity to examine their own methodological assumptions and embrace perspectives from other disciplines; this field of agent evaluation is inherently interdisciplinary, and will necessarily involve some rediscovery and reinvention of existing ideas and insights.
For field-builders—funders, coalitions, and conference organizers—agent evaluation demands its own field of practice, one with higher standards for validity and rigor. Raising this bar can happen by coalescing best practices and fostering conversation and engagement between different disciplinary perspectives.
For leaderboard aggregators, who are central to this emerging ecosystem by shaping which dimensions of evaluation receive attention and in what manner, there is a prime opportunity to incorporate best practices around reporting for downstream adoption, and to help the public understand the rising costs of evaluation.
For deployers and industry evaluators, there is a critical gap for real-world settings to inform evaluation work. By contributing on-the-ground insights and engaging with work in the lab, they can strengthen the discourse in this fast-moving space.
For labs, there is an opportunity to build bridges with independent evaluators and examine the community’s best practices. Successful embedded evaluators will require public legitimacy through independence, transparency, and methodological rigor.
For policymakers, there is a need to develop a clear sense of the current ecosystem and what good evaluations should look like. And for public sector deployments, evaluation needs to be an integrated and continuous part of the process from day one. AISIs can play a key role by pioneering new models for collaboration and inviting new stakeholders into their public input mechanisms within the current ecosystem.
Read the paper here.
the automate vs augment part is the question i try to start with when i build for clients. not "can the agent do this task" but what should the person still own once it's in. and checking the whole trajectory and not just the output is the part nobody budgets for. a workflow that gets the right answer the wrong way is going to break the day i'm not watching.
In the METR trial, agent tools slowed developers. That result should worry deployers most.
Trajectory review is the right standard for evaluators, but it is expensive, and an agent judging another agent inherits the same blind spots. A deployer cannot afford that on every run.
So what is the cheap signal that tells a deployer the benchmark gap has shown up in their own workflow? I would watch how often the people using the agent change or reverse its output.
Do you see override data becoming part of the evaluation ecosystem, or does it stay an internal metric?
Happy to connect, let's talk more about it.